
AI Training Data Services
Vaidik AI provides end-to-end AI training data services for machine learning, computer vision, NLP, speech AI, generative AI, and large language models. We help AI startups, enterprises, and research teams collect, curate, annotate, validate, and prepare high-quality datasets for model training and evaluation.
From multilingual data collection and human-in-the-loop annotation to dataset curation and quality assurance, our teams deliver training-ready data tailored to your model, industry, target market, and quality requirements.
What Are AI Training Data Services?
AI training data services involve collecting, preparing, labeling, validating, and organizing the data required to train machine learning and artificial intelligence models. High-quality training data helps models learn accurate patterns, recognize relevant information, and perform reliably on real-world inputs.
Depending on the AI application, training data may include text, images, audio, video, speech, documents, LiDAR, 3D point clouds, or multimodal datasets. The process can include data sourcing, cleaning, deduplication, annotation, classification, transcription, validation, quality assurance, and dataset formatting.
Vaidik AI combines technology-enabled workflows with human expertise to transform raw or existing data into structured, training-ready datasets. Our AI training data solutions can be customized for specific models, industries, languages, geographic markets, and annotation requirements.
AI Training Data Powered by Human Expertise
Combining AI-driven tools with a skilled global workforce, Vaidik AI ensures the delivery of high-quality datasets across all modalities. Our experienced annotators and domain specialists provide consistent, bias-free data with deep contextual understanding – whether your project demands linguistic fluency, cultural sensitivity, or strict adherence to brand guidelines.
Our High-Quality AI Training Data Solutions

AI Data Collection
We collect custom, diverse, and domain-specific datasets for machine learning and AI applications. Our data collection services support text, image, audio, video, speech, sensor, and other data types based on your project requirements.
Services include:
- Custom dataset sourcing
- Multilingual data collection
- Image and video data collection
- Speech and audio data collection
- Text and conversational data collection
- Web and digital data sourcing
- Participant-based data collection
- Dataset validation and documentation
Data Cleaning & Preprocessing
Raw data often contains duplicates, inconsistencies, irrelevant information, formatting issues, or other quality problems. We prepare datasets before annotation or model training through structured data cleaning and preprocessing workflows.
Our process can include:
- Data deduplication
- Data normalization
- Noise and error removal
- Format conversion
- Metadata organization
- Data filtering
- PII-sensitive data handling
- Dataset structuring
AI Data Annotation & Labeling
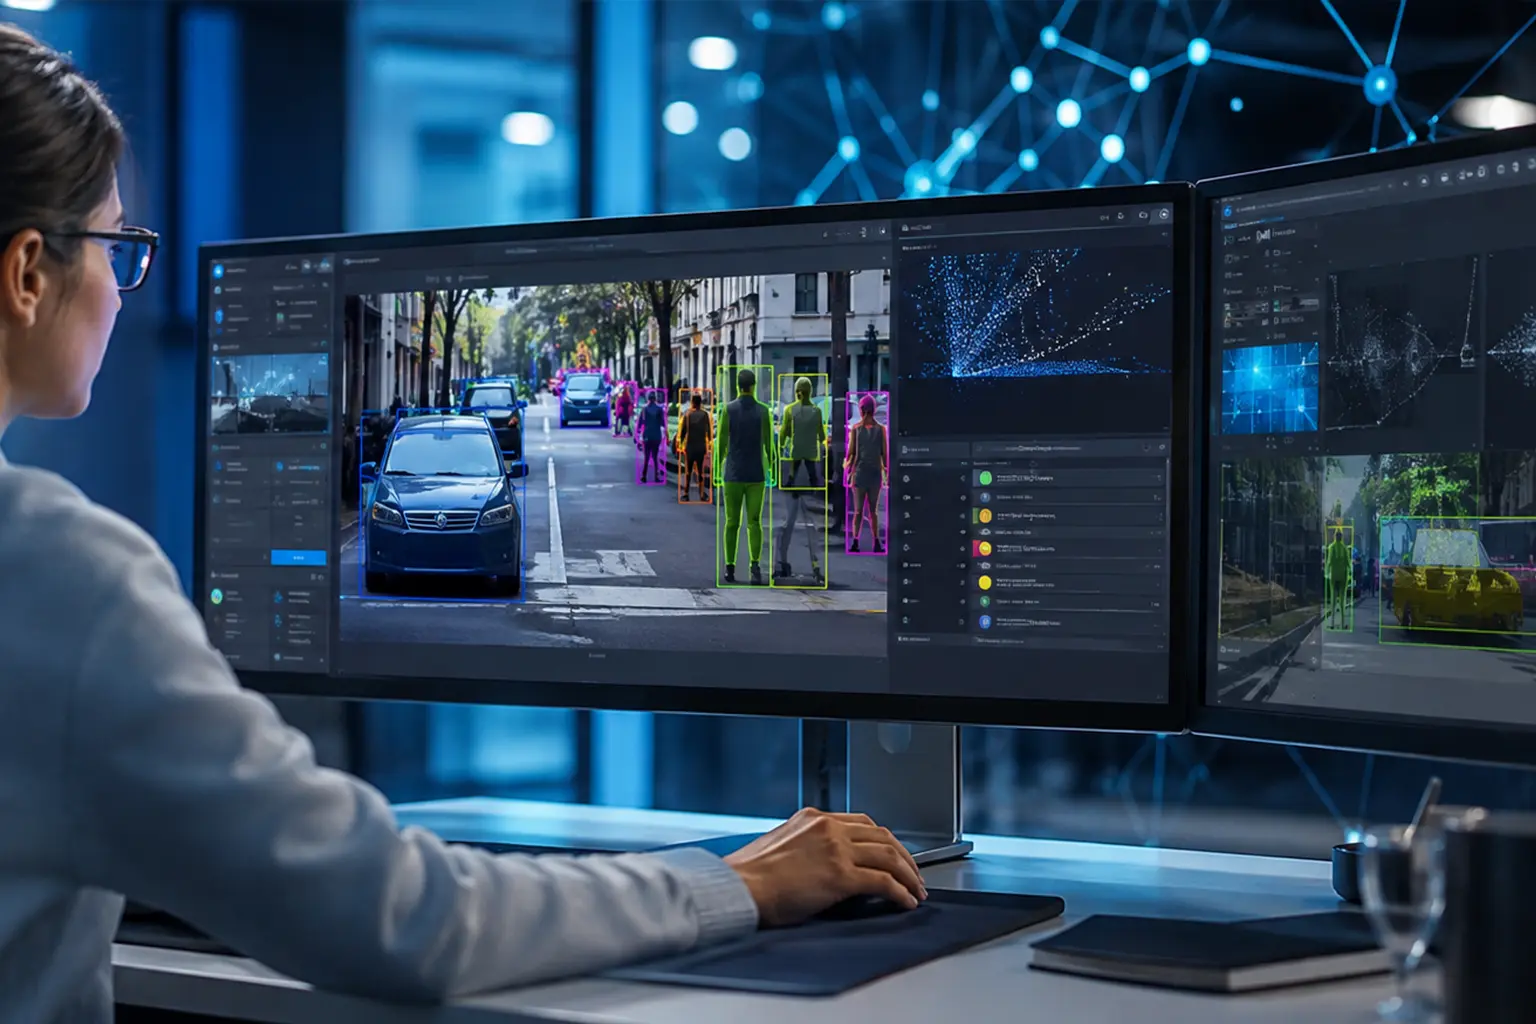
We transform raw datasets into structured training data through human-led and technology-assisted annotation workflows. Our teams support multiple annotation formats for computer vision, NLP, speech AI, document AI, and other machine learning applications.
Annotation capabilities include:
- Image annotation
- Text annotation
- Audio annotation
- Video annotation
- Named Entity Recognition (NER)
- Sentiment and intent classification
- Bounding boxes
- Polygon annotation
- Semantic segmentation
- Keypoint annotation
- Object tracking
- Speech transcription
- LiDAR and 3D annotation
Training Data Curation
We curate datasets based on your model requirements, use case, target audience, industry, and quality standards. Our data curation process helps remove irrelevant or low-quality examples and organizes datasets into consistent, usable structures.
Training data curation can include:
- Dataset selection
- Data filtering
- Data classification
- Metadata enrichment
- Duplicate removal
- Taxonomy development
- Dataset balancing
- Training/validation/test preparation
LLM & Generative AI Training Data
We prepare specialized datasets for large language models and generative AI applications, including conversational AI, instruction-following systems, chatbots, and domain-specific AI models.
Our LLM data capabilities include:
- Instruction-tuning datasets
- Prompt-response datasets
- Conversational datasets
- Preference and ranking data
- RLHF data
- SFT datasets
- Multilingual LLM data
- Safety and alignment datasets
- Domain-specific language datasets
Training Data Validation & Quality Assurance
Our quality assurance workflows are designed to identify annotation errors, inconsistencies, missing information, and guideline deviations before datasets are delivered.
Our QA process can include:
- Annotator training and calibration
- Pilot batches
- Multi-level reviews
- Ground-truth comparison
- Sampling-based quality checks
- Sampling-based quality checks
- Consensus review
- Error analysis
- Bias and consistency checks
- Final dataset validation
Advanced AI Training and Model Development
Beyond data, Vaidik AI also offers end-to-end AI model training and AI trainer support to help organizations develop robust AI systems.
AI Trainer: Our team of expert AI trainers helps in dataset optimization, model evaluation, and continuous learning updates.
AI Model Training: We guide you through the entire AI model training lifecycle from dataset creation to model deployment.
Online AI Training: Through online AI training programs, we empower teams to understand and implement AI model workflows efficiently.
Generative AI Training: Learn the art of creating and fine-tuning generative models through hands-on generative AI training modules.
AI Prompt Training: Our AI prompt training focuses on optimizing prompts for LLMs and generative systems, helping improve output quality.
Training AI Models: We assist businesses in training AI models using large-scale annotated data and domain-specific datasets.
AI Training Datasets: Access high-quality AI training datasets curated to enhance model accuracy and reduce bias.
Why choose us
Domain-Specific Expertise
We understand that every industry has unique data requirements. Whether you're in healthcare, finance, automotive, or e-commerce, our domain experts ensure your training data reflects real-world use cases and standards.
Global Crowd, Local Insight
With a global network of skilled annotators, linguists, and data specialists, we deliver culturally relevant, linguistically accurate datasets in over 150 languages and dialects.
Custom-Tailored Solutions
Your AI project is unique — and so is our approach. We offer flexible engagement models, allowing you to customize data collection, annotation guidelines, quality parameters, and output formats.
Human-in-the-Loop Quality Control
We combine the scalability of automation with the precision of human validation. Our multilayered QA processes help ensure accuracy, consistency, and bias mitigation across your datasets.
Scalable, End-to-End Data Services
From data collection and labeling to evaluation and fine-tuning, we support the entire AI data lifecycle. Whether you’re building a prototype or scaling a production-ready model, we adapt to your growth.
Transparent Communication & Support
Our dedicated project managers work closely with you throughout the process, ensuring seamless coordination, transparent reporting, and quick resolution of challenges.
AI Applications Powered by Quality Training Data
Diverse AI applications depend on precise, high-quality training data to function effectively. At Vaidik AI, we power these intelligent systems with curated datasets that drive performance, reliability, and innovation.
Generative AI
Generative AI relies on diverse, structured datasets to produce creative outputs such as content, synthetic media, and predictions.
Large Language Models (LLMs)
Large Language Models require high-quality language data to understand grammar, facts, and context, enabling them to generate fluent, coherent, and human-like text.
Virtual Assistants
Virtual Assistants are trained on conversational data to understand voice commands, respond naturally, and provide personalized user experiences.
Chatbots
Chatbots use annotated dialogues and user intent data to deliver accurate, context-aware, and engaging interactions across platforms.
Facial Recognition Systems
Facial Recognition Systems depend on varied facial image data to recognize identities, handle lighting and angle variations, and ensure security with minimal bias.
Computer Vision
Computer Vision applications are trained on labeled visual data such as images and videos for tasks like object detection, image classification, and scene understanding.
Data Types Used To Train AI Models
Image / Photos Data

Labeled images serve as ground truth for training AI models in tasks like image classification, object detection, and facial recognition.
Audio / Speech Data

Transcribed and annotated audio recordings are used to train speech recognition, voice biometrics, and natural language understanding systems.
Video Data

Labeled video sequences help AI models perform motion tracking, scene understanding, and real-time object detection.
Text Data

Labeled or unlabeled textual data enables NLP models to understand language, context, sentiment, and generate human-like responses.
Synthetic Data

Artificially generated datasets that simulate real-world conditions, useful for training, testing, or augmenting AI models where real data is scarce or sensitive.
Lidar Data

Lidar (Light Detection and Ranging) data provides high-resolution 3D spatial information used in autonomous vehicles, mapping, obstacle detection, and environmental modeling.
Looking For AI Training Data Services
⏩Domain expertise
⏩Data security And Compliance
⏩ Quality Assurance
⏩ Customized Solutions
⏩ Multilingual Capabilities
Contact us Today To Customize AI Training Data Services to your unique business needs.
Frequently Asked Questions
An AI data trainer prepares, labels, and organizes data so that machine learning models can learn effectively. They ensure that the data used for training is accurate, consistent, and representative of the task the AI is expected to perform. Their work is essential for the AI to understand and make correct decisions.
To create a dataset for AI training, start by defining the problem and identifying the type of data needed. Then collect raw data from reliable sources, clean it to remove errors or inconsistencies, and annotate it if required (e.g., labeling images or tagging text). Finally, structure the data into a usable format like CSV, JSON, or images, and split it into training, validation, and testing sets.
Training data in AI refers to the labeled examples or input-output pairs that a machine learning model uses to learn patterns. This data helps the model understand relationships between inputs and the expected outputs, allowing it to make predictions or classifications when given new, similar data.
Data for AI training can be collected from various sources such as web scraping, public datasets, sensors, APIs, user-generated content, or third-party providers. The method of collection depends on the type of AI model and the domain. It’s important to ensure that the data is relevant, diverse, and legally compliant.
An AI training dataset is a curated collection of data used to train machine learning models. It includes examples that teach the AI system how to perform a specific task. The dataset must be clean, properly labeled, and large enough to capture the variability needed for the model to learn effectively.
Training data in generative AI consists of large volumes of content such as text, images, or audio, which the model learns from to generate new, similar content. The quality and diversity of this data influence how well the AI can create coherent and relevant outputs.
Data training in AI is the process of teaching a machine learning model using labeled data. It’s important because the model’s accuracy and ability to make good predictions depend on the quality of the data it learns from. Without well-prepared training data, even the most advanced algorithms can fail.
In AI, training data is used to teach the model, while testing data is used to evaluate how well the model has learned. Training data helps the model understand patterns, and testing data checks its ability to make accurate predictions on new, unseen inputs, ensuring it can generalize effectively.